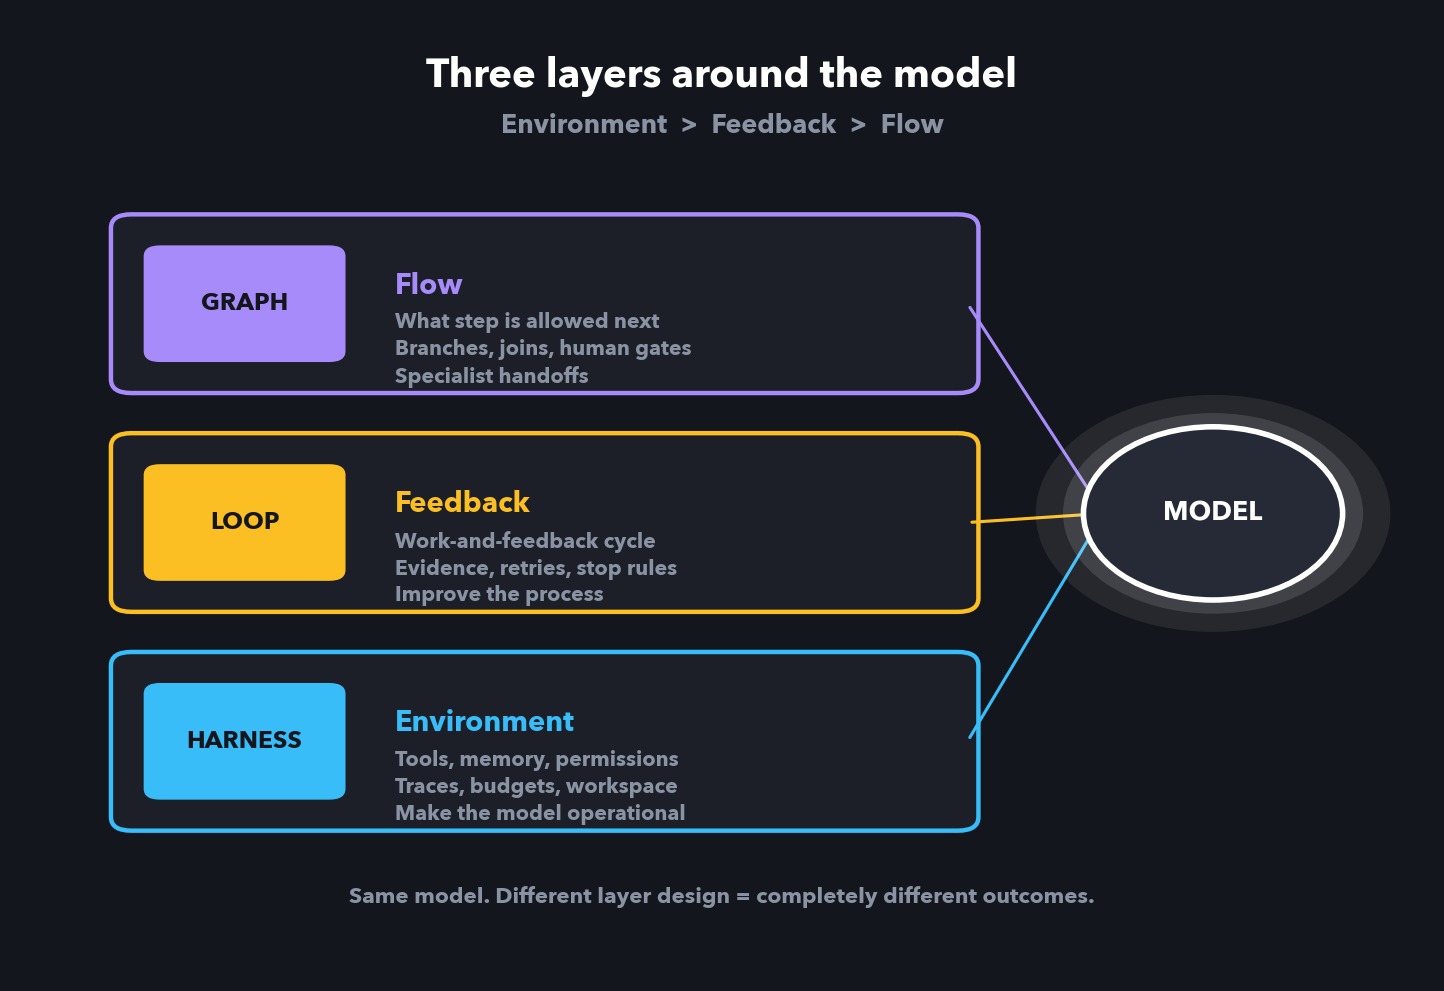
Harness, loop, and graph are not the same layer. Design the middle one so agents improve a process instead of burning tokens on “try again.” The failure mode I keep seeing An agent gets most of the way there. The first draft is close. The tools work. Then it either declares success while the tests are still red, or retries the same broken step until the budget is gone.
Continue reading

This month my feeds filled up with posts about Qwen3.8-27B running at 50 to 75 tokens per second on an RTX 3090 with llama.cpp. Great numbers. My spare Linux laptop has an RTX 3060 Laptop GPU with 6 GB of VRAM, which is not even half of what the Q4 weights need. I wanted to know if the model could run on it at all. It can. As I write this, a coding agent on my LAN is talking to Qwen3.

Continue reading

Moisés Vargas

Life Long Learner

Machine Learning Engineer

Medellín